
On this page
Distinguish the Text Value from Its JSON Representation
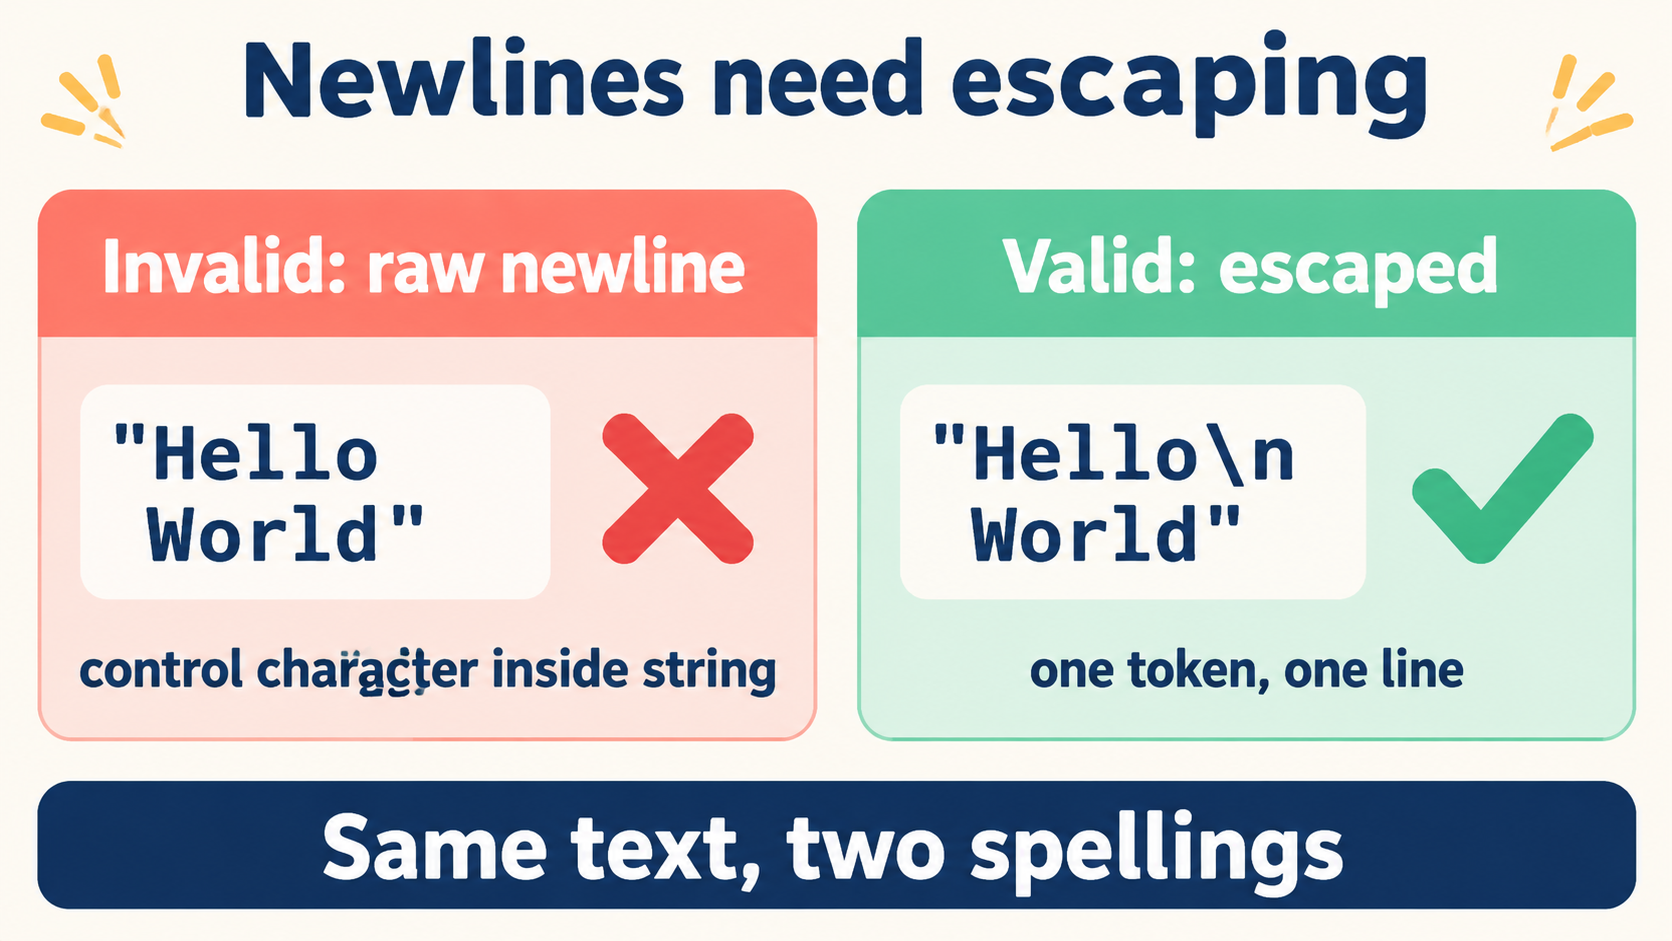
To store multiline text in JSON, pass the original string to a JSON serializer. In the resulting JSON text, a newline is represented by the escape sequence \n. Parsing that JSON recovers the newline character. Placing a raw line break directly inside a quoted JSON string makes the document invalid.
The key check is whether the recovered value contains the characters your application needs — which means following one message through three stages before deciding whether its escaping needs repair:
1. The original text value:
red
blue

2. The serialized JSON text:
{"message":"red\nblue"}

3. The value recovered after parsing:
red
blue
The message contains a newline between the two words — a character belonging to the text value you want to store. Inside the quoted value, the visible characters backslash and n represent that newline, so the serialized document occupies one physical line while representing a two-line message. After a parser reads the document, the message value contains the newline again, and displaying the recovered value as text can show the two lines once more.
Each stage has its own failure mode, and they do not share symptoms. A mistake at stage two produces invalid JSON or a wrongly escaped character; a mistake at stage three produces a value that parses fine but differs from the input. That is why the repair always starts by naming the stage — “the document won’t parse” and “the parsed message is wrong” lead to completely different inspections, and conflating them is how a correct document gets “fixed” into a broken one.
The distinction matters when inspecting an apparent mismatch. Are you looking at JSON source text, a debugger’s representation, or the parsed string value? Establish which layer is displayed before counting backslashes or replacing characters. For this example, the intended result after one parse is a message with a newline between the words, so the visible \n in JSON source is the representation of that character — its presence is consistent with preserving the original text, not a defect.
Why an Unescaped Newline Fails Inside Quotes
JSON strings use double quotes, and control characters within them must be escaped. A raw LF character inside those quotes makes the JSON invalid. A raw carriage return also requires escaping; its JSON escape is \r.
// valid:
{"message":"red\nblue"}
// intentionally invalid — the quoted value contains a raw newline:
{"message":"red
blue"}
JSON.parse('{"message":"red\nblue"}'); // works — \n is the escape
JSON.parse('{"message":"red\nblue"}'); // SyntaxError — real newline in source
// single quotes don't fix it; JSON has no triple quotes either
When a parser reports an error around a line break, inspect whether that break falls inside the string’s quotes. Changing the double quotes to single quotes does not repair standard JSON, and standard JSON provides neither triple-quoted strings nor raw multiline-string syntax.
Newlines Can Format the Surrounding Document
Whitespace between JSON tokens serves a different purpose:
{
  "message": "red\nblue"
}
Here, the physical newlines around the property format the document; the escaped newline inside message represents content in the value. Expanding the document’s layout does not permit raw control characters inside its quoted strings — the two kinds of line break live at different layers, and confusing them is the root of most “it worked until I formatted it” reports.
Use the reported error position to narrow the inspection: check the surrounding quotes, identify whether the character belongs to the message or the document layout, and correct that specific mismatch.
Let the Serializer Handle Multiline Text
Keep the message as a language string and pass the containing object to the serializer — it produces JSON text and handles escaping for newlines, quotes, tabs, and backslashes. In JavaScript:
const message = "red\nblue";
const payload = JSON.stringify({ message });

console.log(payload);
console.log(JSON.parse(payload).message === message);
Expected output:
{"message":"red\nblue"}
true
In the declaration, \n supplies the newline in message; serialization represents that character with the JSON escape; JSON.parse() recovers the object; the equality comparison checks the recovered message against the original.
A template literal can also provide multiline input:
const messageFromTemplate = `red
blue`;
const payloadFromTemplate = JSON.stringify({ message: messageFromTemplate });

console.log(payloadFromTemplate);
console.log(JSON.parse(payloadFromTemplate).message === messageFromTemplate);
Expected output:
{"message":"red\nblue"}
true
The template literal belongs to JavaScript source syntax; its use changes nothing about the serialized JSON string’s rules. Python’s triple-quoted strings work the same way with json.dumps() — the triple quotes belong to the program, the JSON output uses ordinary double-quoted strings with escaped newlines:
import json

message = """red
blue"""
payload = json.dumps({"message": message})

print(payload)
Expected output:
{"message": "red\nblue"}
The space after the colon is document formatting; it does not add a space to the beginning of the message. That detail is easy to verify and easy to get wrong: pretty-printing decisions belong to the document layer, while the message’s own leading and trailing characters belong to the value, and the serializer keeps them separate automatically. Before adapting the example to a larger text block, check whether the input contains an intended initial newline, indentation, blank lines, or a final newline — establish the desired text before passing it to the serializer, because every one of those characters will be faithfully preserved, including the ones you did not intend. Keep the original input available while investigating a mismatch: compare the recovered field directly with that input, then inspect any transformations performed before serialization. That is a concrete preservation check instead of relying on how the JSON happens to look in an editor.
Tell a Newline Escape from Literal Backslash-n Text
A newline and the visible characters backslash followed by n are different possible message contents, and JSON can represent either. First determine which one the input is supposed to contain:
| JSON string source | Value after one JSON parse |
|---|---|
"red\nblue" |
red, a newline, then blue |
"red\\nblue" |
red, a literal backslash, the letter n, then blue |
Two consecutive backslashes in JSON string source encode one literal backslash; in the second row, that recovered backslash is followed by an ordinary n, so the parsed value contains the visible sequence \n rather than a newline:
JSON.parse('"red\\nblue"'); // 'red\nblue' — newline character, length 7
JSON.parse('"red\\\\nblue"'); // 'red\\nblue' — backslash + n, length 8
// one backslash difference in source, one character difference in value
Embedding JSON text in JavaScript source introduces another layer: JavaScript processes its string escapes before the JSON parser receives the resulting text:
const payload = '{"message":"red\\nblue"}';
const recovered = JSON.parse(payload).message;

console.log(payload);
console.log(recovered === "red\nblue");
Expected output:
{"message":"red\nblue"}
true
The doubled backslash in the JavaScript source leaves one backslash in the JSON text; JSON then reads that backslash with the following n as a newline escape. Trace the layers separately — language source, JSON text, parsed value — because counting slashes without identifying the layer can lead to changing an already correct value.
Also ask whether an already serialized payload has been passed through a serializer again. Serializing JSON text treats that text as the next input value; if one parse returns a string where the consumer expects an object, inspect the serialization steps before adding another parse. Decide what one parse should recover, then make producer and consumer agree on that result.
Preserve the Line Endings Your Application Needs
Write down which characters must survive before choosing a repair — this is the step teams skip, and the step that decides whether the fix is correct. Your message may require LF, CRLF, blank lines, or a final newline; a similar-looking display is not enough to establish that those characters were preserved. Git diff viewers, terminals, and copy-paste all normalize line endings silently, so the evidence has to come from character inspection, not appearance:
| Intended message content | JSON string representation |
|---|---|
| LF between the words | "red\nblue" |
| Carriage return followed by LF | "red\r\nblue" |
| A blank line between the words | "red\n\nblue" |
| A newline after the last word | "red\nblue\n" |
The consecutive escapes \r\n represent a carriage return followed by a line feed; preserving that pair and intentionally converting it to LF are different application requirements.
Compare recovered characters with the input, including a message containing quotes and a backslash:
const samples = [
  ["LF", "red\nblue"],
  ["CRLF", "red\r\nblue"],
  ["Blank line", "red\n\nblue"],
  ["Final newline", "red\nblue\n"],
  ["Quotes and backslashes", 'say "red"\nslash: \\']
];

for (const [label, message] of samples) {
  const payload = JSON.stringify({ message });
  const recovered = JSON.parse(payload).message;
  console.log(label, recovered === message);
}
Expected output:
LF true
CRLF true
Blank line true
Final newline true
Quotes and backslashes true
These comparisons check the recovered strings against the exact values supplied to the serializer — five cases, five trues, and the fifth one matters most: a message containing quotes and a backslash exercises every escape the serializer owns, and manual repair code rarely handles all of them at once. If the application requires normalization, make that an explicit processing decision and compare against the intended normalized value, and separately inspect any earlier processing that might have changed the original input.
Manual newline replacement is fragile precisely because quotes and backslashes also require correct escaping — let the serializer handle the complete value, and include representative punctuation in preservation checks. When a long line appears to break in an editor, ask whether a newline is stored in the value or the editor is merely wrapping the display, and inspect the input characters before treating that visual break as content needing an escape:
// display wrap vs. real newline:
const v = recovered.message;
v.includes('\n');        // false → the editor wrapped the display only
[...v].length;           // character count settles it
Separate String Content from Pretty Printing and JSON Lines
Pretty printing adds whitespace between JSON tokens without changing the string value — you can expand a document’s layout while keeping newlines inside its strings escaped:
const message = "red\nblue";
const pretty = JSON.stringify({ message }, null, 2);

console.log(pretty);
console.log(JSON.parse(pretty).message === message);
Expected output:
{
  "message": "red\nblue"
}
true
The physical lines around the property make the document easier to read; the visible \n within the quotes continues to represent the message’s newline, and the equality comparison confirms the formatted document round-trips.
JSON Lines also requires newlines embedded in string values to be escaped — choosing the format does not permit raw control characters inside quotes. Before applying a formatter, confirm the consumer’s expected document format and layout requirements; if the input is intended for JSON Lines, ask what formatting that consumer accepts rather than assuming pretty-printing suits the entire input. Keep two inspection questions separate: does the document layout satisfy the consumer, and does the parsed message contain the intended characters? Changing layout serves readability; checking the recovered value establishes preservation.
Choose One Text Block or Independently Meaningful Lines
Use a single string when the consumer needs the message as one text block. Consider an array when line order matters and each line has an independent meaning — the data contract chooses:
{"message":"red\nblue"}
{"lines":["red","blue"]}
| Consumer requirement | Representation to consider | Agreement to verify |
|---|---|---|
| Recover the original message unchanged | One string | Required line endings, blank lines, and final newline |
| Address individual lines in order | An array of strings | Meaning and order of each element |
| Reconstruct original text from lines | An array with an explicit reconstruction agreement | How separators and the final newline are preserved |
Array elements remain JSON strings, so their contents still follow JSON escaping rules — choosing an array does not remove the need to serialize each string correctly. If you choose separate lines, agree on how blank lines and a final newline should be represented, and ask which separators the consumer should use to reconstruct the original text. Establish those decisions before converting an existing text field to an array; a consumer expecting message as a string needs agreement before receiving lines as an array, because the two examples express different expectations about how the content will be used.
Before sending the result, verify three things: the input contains the intended characters, the serialized document matches the expected format, and one parse returns the intended value and shape. Paste the serialized fixture into the JSON Inspector on this site — the raw pane shows the escaped \n on one line while the tree view shows the recovered value with its newline intact, both layers side by side, all local.