
On this page
Why Strict JSON Rejects Comments
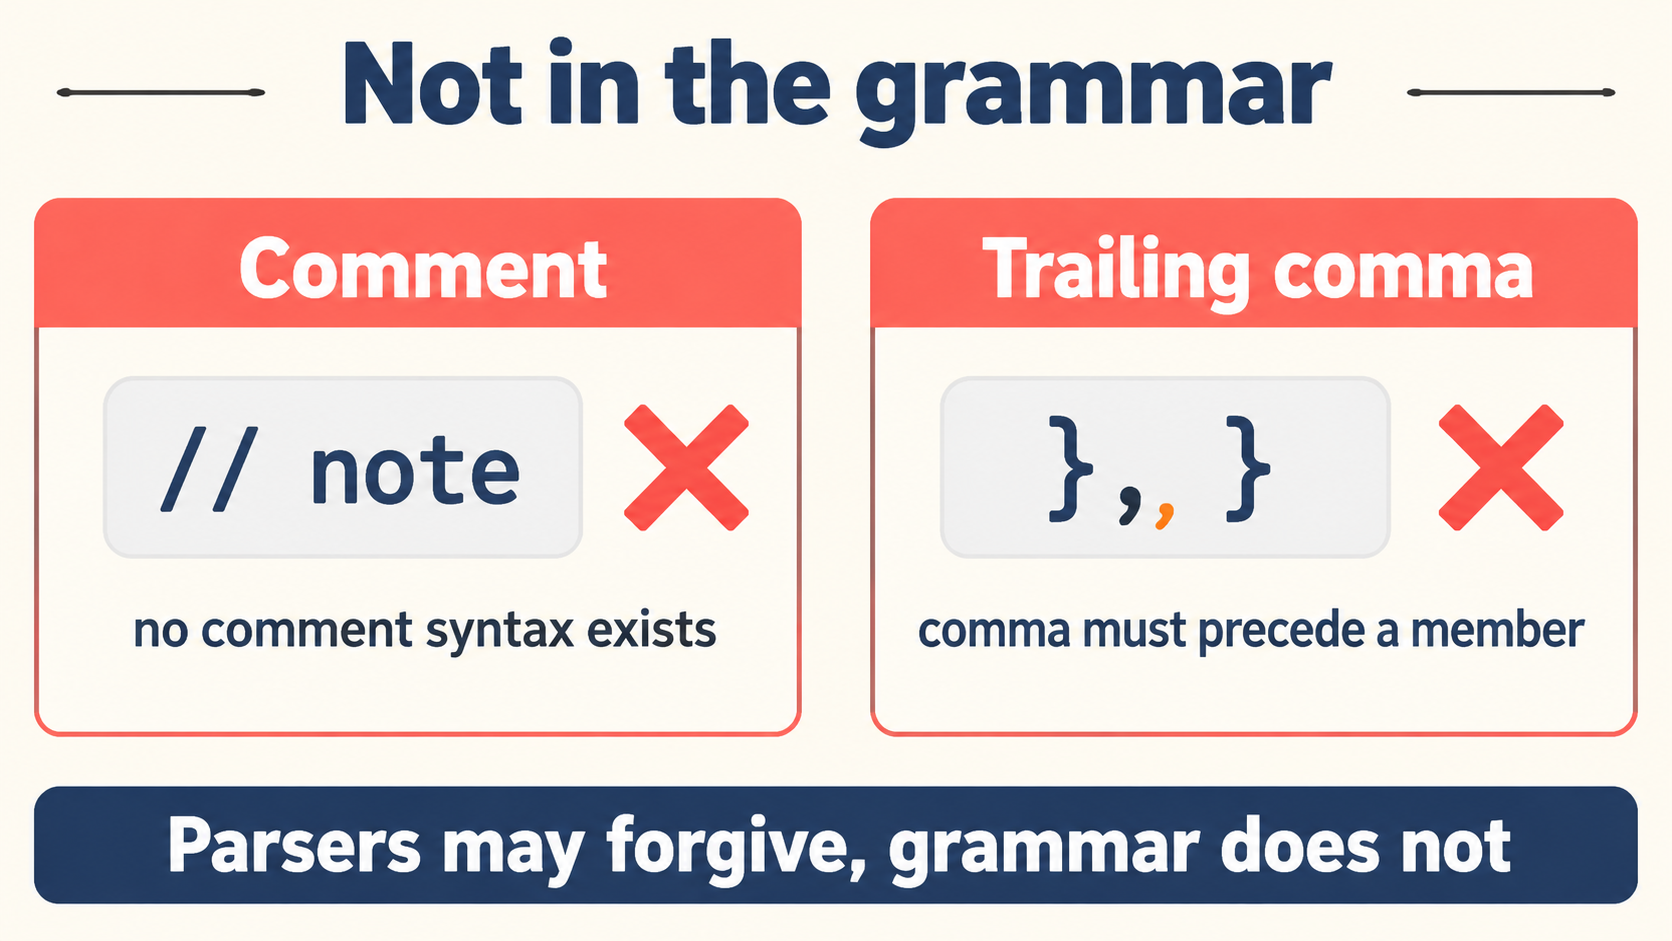
Strict JSON rejects comments because its grammar does not recognize them. It rejects trailing commas because a comma separates one member or value from the next: a closing bracket or brace cannot supply the missing item. These are syntax rules, so changing indentation cannot resolve either problem.
The practical solution is to identify the input format, remove only the unsupported syntax that its rules permit, and validate the result. That requires recognizing strings and escapes before interpreting apparent comment markers or commas. The examples below are proposed inputs with expected results, not reports of executed tests.
Strict JSON has no comment production — there is no grammatical rule that tells a strict consumer to accept an annotation beginning with // or /*. A comment therefore changes the accepted syntax rather than merely changing its presentation. JSON recognizes exactly four whitespace characters: space, horizontal tab, line feed, and carriage return. At a position where whitespace is permitted, those characters provide spacing; comment markers do not become whitespace simply because a reader understands them as explanatory notes:
// proposed input in a dialect that permits comments:
{"enabled": /* explanation */ true}

// corresponding strict JSON:
{"enabled": true}
The conversion removes the annotation and leaves whitespace between the surrounding tokens — it does not ask the strict consumer to interpret the annotation. The distinction between a comment and an extra space comes from the grammar, not from how much information the text carries: a space is recognized whitespace, a comment is unsupported syntax, and even a short harmless annotation stays outside strict JSON when it appears outside a string. Before cleaning an input, establish whether comments are permitted by its declared source dialect — otherwise a converter risks treating arbitrary malformed text as something it has permission to discard.
// the grammar's position, observed:
JSON.parse('{"enabled": true /* x */}'); // SyntaxError
JSON.parse('{"enabled":  true    }');    // fine — whitespace is legal
// one is a token the grammar ignores; the other is a token it never defined
Why a Trailing Comma Leaves Something Missing
In a JSON object, a comma separates members and must be followed by another member. In an array, it separates values and must be followed by another value. A trailing comma leaves that requirement unfulfilled:
JSON.parse('[1,2,]')
// Expected outcome: a SyntaxError — the final comma requires
// another value before the closing bracket

JSON.parse('[1,2]')
// Expected outcome: a two-element array containing 1 and 2
The same reasoning applies to an object:
// {"count":2,} — the comma after 2 requires another member
{"count":2}   // removing the trailing separator produces this
The interpretation the comma means this item is finished is the source of the mismatch: in strict JSON, the comma connects an item to a following item and never terminates a collection — the closing delimiter finishes the object or array without an extra comma. This also explains why deleting a trailing comma differs from supplying missing data: a controlled conversion may remove an allowed source-dialect separator, but it should never invent a member or value to satisfy an otherwise incomplete input.
Why Configuration Files Can Follow Different Rules
Acceptance depends on the consumer and its input contract. JavaScript object and array literals permit trailing commas — that does not make the same text valid strict JSON. JSONC configurations and configurable parsers add a practical subtlety: comment handling and trailing-comma handling are separate questions, and permission for one feature does not establish permission for the other. When working with System.Text.Json, verify the effective parser settings for each feature instead of assuming a successful configuration load establishes strict JSON compatibility:
| Context | What to establish | Practical consequence |
|---|---|---|
| Strict JSON | Comments and trailing commas are rejected | Both must be absent from the submitted text |
| JavaScript object or array literal | Trailing commas are permitted | The literal still needs review before use as strict JSON |
| JSONC configuration | The consumer’s rules for comments and trailing commas | Check the two features independently |
| System.Text.Json | The settings used by the actual parsing operation | Confirm behavior where the text is consumed |
// JavaScript tolerates; strict JSON does not:
const literal = { count: 2, };   // valid JS object literal
JSON.parse('{"count":2,}');      // SyntaxError — different grammar
When an editor accepts a file another consumer rejects, each answered its own question: the editor or configuration loader validates its accepted input; the strict JSON consumer validates the grammar. Record the intended source dialect before conversion and the required output format afterward — that gives each edit a clear justification and avoids an undefined promise to accept anything that looks close to JSON.
Comment-like Text Inside Strings Must Survive
A converter must distinguish syntax outside strings from characters belonging to string contents — otherwise an apparent cleanup can change the data it was supposed to preserve. Use an example like this when reviewing proposed behavior:
{
  "url": "https://example.test/a",
  "marker": "/* keep */",
  "ending": ",}",
  "message": "She said \"keep // this\"."
}
The expected result is unchanged text. The URL contains //, the marker contains /* keep */, and another value contains ,} — none of those appearances authorizes a deletion because they occur inside strings.
The message adds an escape-related check: its escaped quotation marks must remain within the string and must not be mistaken for the end of that string. A scan that simply searches for the next quotation mark does not provide the required distinction:
// the state machine a real converter needs, in miniature:
function findStringEnd(src, start) {         // start: index of opening quote
  for (let i = start + 1; i < src.length; i++) {
    if (src[i] === '\\') { i++; continue; }   // skip escaped char
    if (src[i] === '"') return i;             // real string end
  }
  return -1; // unterminated → reject, do not guess
}
// everything between start and the return value is DATA — hands off
For syntax-only cleanup, preservation means comparing the complete original and resulting string tokens, including their quotation marks and escape sequences — preserving only an interpreted value is a different requirement and does not demonstrate that the original text survived unchanged. Broad replacements targeting everything after //, everything between apparent block-comment markers, or every ,} sequence fail to establish whether those characters are syntax; recognize their context first.
Remove Unsupported Syntax with Token Awareness
Design the converter around an explicitly declared source dialect: specify which comment forms and trailing separators it may remove, then reject inputs outside that contract. A useful conversion procedure has distinct responsibilities:
- Track strings and escapes. Copy string tokens unchanged; interpret apparent comment markers and structural punctuation only in the appropriate state outside strings.
- Track comment boundaries. Recognize comments according to the declared dialect; stop if a comment requiring a closing boundary never receives one.
- Replace comments with whitespace. Retain line breaks rather than joining the surrounding text directly.
- Track grammatical context. Determine whether a comma follows a completed member or value and whether the next significant token closes the corresponding collection.
- Preserve other tokens. Copy number tokens and all unaffected text without evaluating or reformatting their values.
- Validate the result. Submit the complete converted text to a strict JSON parser.
Why leave whitespace behind? Consider the deliberately malformed fragment 1/* note */2: deleting the comment without a replacement would create 12, silently turning separate tokens into a different number. Replacing the comment with a space leaves 1 2, allowing validation to expose the unresolved syntax problem:
// the silent-merge trap:
'1/* note */2'.replace(/\/\*[^*]*\*\//g, ''); // '12' — a DIFFERENT number
'1/* note */2'.replace(/\/\*[^*]*\*\//g, ' '); // '1 2' — parser will judge
How much context does a trailing comma need? Finding a comma before a closing delimiter is insufficient: the preceding member or value must be complete, and the surrounding structure must permit that one separator under the source dialect. For example, [1,,] contains repeated separators and should stop conversion — repeatedly deleting commas until the text parses would hide the missing value. Use a scanner and grammatical checks appropriate to the declared input, and avoid eval and broad text replacements: neither is the controlled syntax conversion described here.
A Minimal Conversion with Expected Output
The following input belongs to a permissive dialect that allows the shown comment and trailing separators — it is not strict JSON:
{"url":"https://example.test/a",/*note*/"items":[1,2,],"text":",}",}
For a converter explicitly supporting those features, the expected output is:
{"url":"https://example.test/a", "items":[1,2],"text":",}"}
The intended edit replaces /*note*/ with one space, removes the trailing separator from the items array, and removes the final trailing separator from the object. The other commas remain because they still separate members or values.
| Role | Tokens to preserve exactly |
|---|---|
| Member names | "url", "items", "text" |
| URL value | "https://example.test/a" — the // survives |
| Text value | ",}" — the comma and brace survive |
The number tokens 1 and 2 should also remain unchanged. This example defines an expected transformation, not evidence that an implementation has passed it — review both parts of the result, strict syntax and preserved data, because a valid output alone would not reveal whether an overly broad replacement had damaged a string.
Validate the Result Without Guessing Missing Data
Conversion should stop when resolving an input would require inventing content. Removing a declared source-dialect feature is a bounded operation; choosing an absent value or reconstructing an unfinished string is not. Include negative cases alongside the successful example:
| Proposed input | Problem | Expected handling |
|---|---|---|
[1,,2] |
Repeated separators leave a value missing | Reject |
[,2] |
The first array value is missing | Reject |
[1,,] |
Repeated separators cannot be treated as one trailing comma | Reject |
{"item":,} |
The member has no value | Reject |
{"item":1,/* unfinished |
A block comment is unterminated | Reject |
{"text":"unfinished |
A string is unterminated | Reject |
Do not insert a guessed value, add a quotation mark, or repeatedly remove punctuation to make these cases pass. Preserve a clear distinction between supported conversion and malformed input:
// each rejection, confirmed by a strict parser:
['[1,,2]','[,2]','[1,,]','{"item":,}'].every(s => {
  try { JSON.parse(s); return false; }   // parsed — bad sign for the test
  catch { return true; }                 // rejected — as expected
}); // true — the grammar agrees with the conversion's stop list
Check Syntax and Preservation Separately
After conversion, validate the entire output as strict JSON, then compare the original and resulting string and number tokens, excluding only the comments and trailing separators intentionally removed. These checks answer different questions: whether the output is accepted, and whether the conversion preserved its data.
For a native parse-and-reserialize workflow, verify numeric precision separately before adopting it as a cleanup method. If parsing has rounded a numeric value, serializing that value cannot reconstruct the original number token — a syntax-only converter can instead copy the original numeric text while making its narrowly defined edits:
// why parse-reserialize is not a safe cleanup:
JSON.parse('{"id":9007199254740993}');
// {id: 9007199254740992} — rounded BEFORE any formatting decision
// a token-aware converter copies the original digits and touches nothing
If the input contract does not establish whether a particular number survives native parsing accurately, ask for that requirement and verify it — do not assume a successful parse proves numeric fidelity. A useful completion report should identify the unsupported syntax removed, confirm strict validation, and state whether token preservation was checked; that makes the transformation reviewable without treating successful parsing as proof of every other property. Paste both the permissive input and the converted output into the JSON Inspector on this site: the raw panes show the removed syntax side by side, the strict parser confirms acceptance, and the token comparison stays on one screen — all locally, with the original text never leaving the machine.