
On this page
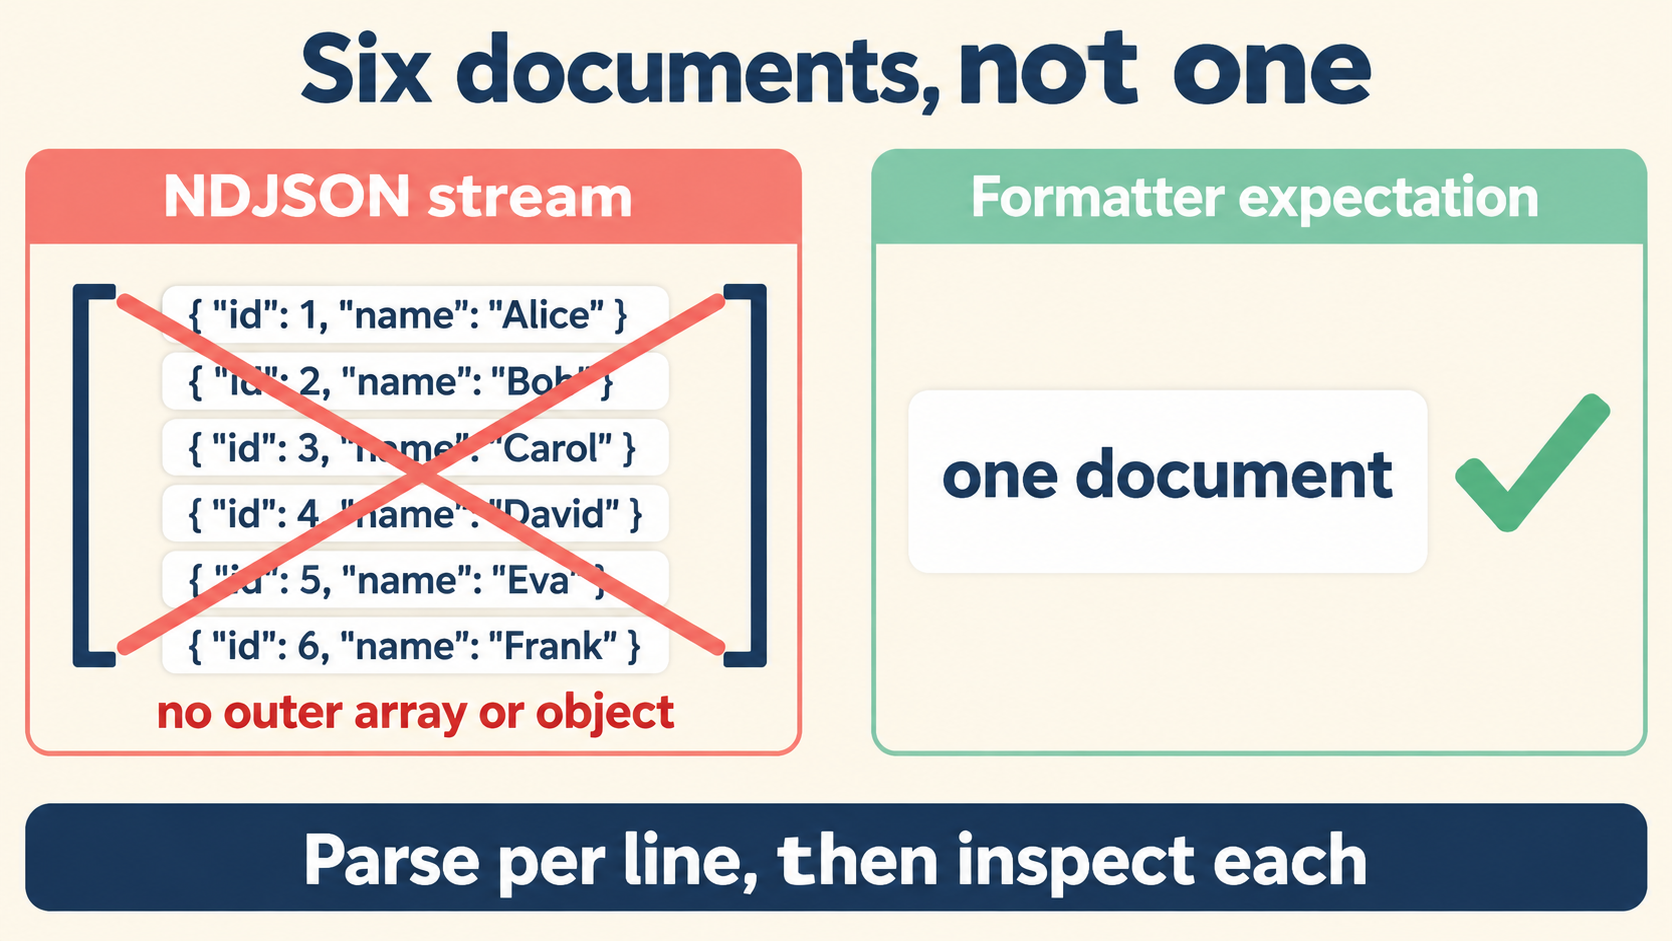
Valid Records, Invalid Document
An NDJSON or JSONL log can fail in a JSON formatter even when every individual record is valid. The mismatch usually lies in how the input separates records: NDJSON uses newlines between independent JSON values, while a JSON document contains exactly one top-level value. Paste several records into a formatter that expects one document and the error arrives right after the first record — which is why the failure looks like malformed data when it is actually a framing problem.
The opening move is to test records individually and check their boundaries. If the receiving interface genuinely requires one document, the resolution is to combine validated records into a JSON array. Both approaches appear below with expected results, while malformed records, empty lines, duplicate keys, and number preservation stay as separate questions throughout — conflating them is how a ten-minute diagnosis becomes an afternoon.
Consider these two JavaScript expressions:
JSON.parse('{"id":1}');
// Expected: an object whose id property is 1

JSON.parse('{"id":1}\n{"id":2}');
// Expected: throws a SyntaxError
The second input contains two independent top-level values. Its newline separates the records but does not merge them into one JSON document. A conventional parser accepts the first value and then rejects the additional input; the exact wording of that rejection varies by parser, so diagnose the input structure rather than trusting a particular message.
Test {"id":2} independently as well. If both records parse alone, you have evidence of a framing mismatch: each record is acceptable separately, but their combination is unsuitable for an interface expecting one document. That distinction determines the next action — a malformed record needs correction at its original location, while valid independent records need an inspection workflow or a conversion into one enclosing value. Reformatting the same combined text without changing its structure resolves nothing.
Check Record Boundaries Before Splitting Lines
Before applying any line-based example, establish that every physical line contains one complete JSON value. A log showing indented events spread across several lines needs a different boundary check: splitting each line would separate parts of an event instead of separating complete records.
Compare the two layouts:
{"id":1}
{"id":2}
{
  "id": 1
}
{
  "id": 2
}
The first provides one complete value per physical line. The second spreads values across multiple lines. Applying the same split-and-parse operation to both layouts does not test the same thing — the operation that works on the first destroys the second.
Ask how the export was produced and whether it promises one complete value per line. Do not assume arbitrary multiline console output follows that arrangement. If indentation has spread events across lines, obtain a record-oriented export or establish the event boundaries another way before continuing. Pretty-printed input and NDJSON are different formats that merely share a file extension in some pipelines, and treating one as the other produces errors that look like data corruption but are pure framing mistakes.
An Escaped Newline Is Part of a Value
One more distinction hides inside string content:
{"message":"first\nsecond"}
{"id":2}
The visible \n sequence inside the quoted message is an escaped newline within that string — two characters, backslash and n, not a record boundary. The physical line break after the first closing brace is what separates the records. These two uses of a newline must never be confused when identifying boundaries; a naive splitter that treats every backslash-n as a break will slice a valid record into fragments, and a splitter that ignores real line breaks because it has been taught to distrust them will glue records together.
// a correct boundary rule in one line:
// split ONLY on real \n characters — never on the two-character
// sequence backslash+n inside a quoted string
'{"message":"a\\nb"}\n{"id":2}'.split('\n');
// ['{"message":"a\\nb"}', '{"id":2}'] — exactly two records
When a record count comes out wrong, recount manually: find the physical line breaks, exclude any inside quoted strings, and compare that count with what your splitter produced. The discrepancy usually names the bug on the spot.
Validate Each Record and Keep Its Line Number
Once one complete record per line is confirmed, validate records independently — and keep the original line position alongside each result so any error remains traceable to the input. This example deliberately includes a malformed second record:
const lines = ['{"id":1}', '{"id":}', '{"id":3}'];

lines.map((s, i) => {
  try {
    JSON.parse(s);
    return [i + 1, 'valid'];
  } catch {
    return [i + 1, 'invalid'];
  }
});
Expected result:
[[1,"valid"],[2,"invalid"],[3,"valid"]]
The failure on line 2 is caught within that record’s validation step, which allows line 3 to be checked. You can investigate the malformed record while retaining access to the valid records around it — per-record try/catch is what makes the report complete instead of first-error-and-stop.
Assign line numbers before removing or selecting lines. Otherwise a reported position may describe the filtered list instead of the original input — especially confusing when empty lines appear before a malformed record. For an error report, retain enough information to connect the result to its source: the original line number, whether parsing succeeded, and the record text where appropriate. Keep the untouched input available for comparison.
Note the report’s scope deliberately: it covers syntax acceptance only. It does not choose an empty-line policy, assemble an output document, or establish whether a later inspector preserves every detail of the original representation. Those are separate decisions with separate sections below.
Combine Validated Records into One JSON Array
When the receiving interface requires a single JSON document, an enclosing array can hold the independent records. Square brackets surround the collection; commas separate adjacent elements. For nonempty, single-line records containing small integers, the minimal conversion is:
const text = '{"id":1}\n{"id":2}';

JSON.stringify(text.split('\n').map(s => JSON.parse(s)));
Expected return value, shown as a JavaScript string:
'[{"id":1},{"id":2}]'
The returned text has one top-level value: an array containing two objects. Each original record becomes one array element, in original order. The brackets and commas supply the structure needed to represent the collection as one document.
Understand the example’s limits before reusing it. It assumes every split line is a complete, nonempty record; a malformed record makes its parse throw, stopping the expression before any conversion completes — use the independent validation above first when you need a report covering all records. An empty-line decision is also required before this approach touches input containing blank lines; do not discard them silently as an incidental cleanup step. And the demonstration uses small integers: its success illustrates record framing and array construction, not preservation of large numbers or their original numeric spelling, which needs a separate check of the parser and serializer you actually intend to use.
Do not assume every NDJSON record is an object, either. Records can be arrays or primitives. A record-preserving conversion keeps each complete value as one element:
const text = '42\n[1,2]';

JSON.stringify(text.split('\n').map(s => JSON.parse(s)));
// '[42,[1,2]]' — two records, two elements; the nested array stays nested
Flattening the second record’s elements into separate outer elements would change the record structure. If an ingestion service flattens array records, treat that as a separate ingestion policy and verify its behavior before assuming equivalence with this conversion.
Empty Lines Deserve an Explicit Policy
Empty lines need their own handling decision, kept distinct from the report of a nonempty record that fails to parse. Two defensible policies:
| Chosen handling | What the workflow should report |
|---|---|
| Reject empty lines | Identify their original line numbers and require resolution before conversion |
| Skip empty lines | Record that they were skipped and retain original line numbers for remaining records |
Also decide whether the policy covers whitespace-only lines, and state that choice explicitly rather than leaving readers to infer it from a cleanup operation. A line containing a single space is not obviously “empty” to every consumer, and the two policies diverge on exactly such inputs.
For input containing a valid record on line 1, an empty line on line 2, and another valid record on line 3, skipping the empty line should not rename the last record as source line 2. Output positions and original input positions serve different purposes — the first organizes the converted array, the second makes errors traceable. A report that conflates them sends an investigator to the wrong line, which in a ten-thousand-line export is a genuinely expensive mistake.
// keep both counters, keep them separate:
let out = 0;
for (const [i, s] of lines.entries()) {
  if (!s.trim()) continue;        // policy: skip empties
  out++;                          // output position
  // i + 1 is the original line — report THIS one in errors
}
Framing Errors, Inspector Policies and Input Size
After correcting record framing, inspect either one independent record or the constructed array in a JSON formatter. If an unexpected result remains, investigate it as a separate concern instead of repeatedly changing record separators. Three useful checks address three different questions:
| Concern | Question to investigate |
|---|---|
| Record framing | Does the interface expect one value, and did you supply several independent values? |
| Duplicate keys | What does the inspector document about accepting, reporting, or retaining repeated keys? |
| Number preservation | Does the processing path preserve the values and numeric spelling your task requires? |
A successful parse shows that the selected parser accepts that input — it does not establish every property of the resulting display or serialized output. For duplicate keys, consult the inspector’s stated handling and compare the original record with what it displays or returns; do not infer the policy from a successful test using records without duplicate keys, and ask for clarification before relying on unspecified behavior. Apply the same discipline to numbers: the small-integer examples here demonstrate neither large-number handling nor retention of a token’s original spelling. Keep the original text when those details matter, and verify the actual parser, inspector, and output path involved.
Choose the workflow from the downstream interface’s requirements:
| Your immediate need | Suitable approach |
|---|---|
| Find a malformed record in a log | Validate records separately and report original line numbers |
| Examine one event in a formatter | Supply that complete record by itself |
| Supply a collection as one JSON document | Convert validated records into an enclosing array |
| Investigate a large export | Prefer incremental validation and inspection where supported |
Account for input size, too. The short split-and-collect example holds the input and all collected records in memory — fine for explaining the transformation, but not a capacity guarantee for a large export or a particular formatter. For bigger inputs, check whether the available tools support incremental inspection and how they retain record locations, and confirm the receiving interface’s accepted structure before collecting everything into an array merely to inspect one failing event.
Before handing off converted output, verify three things: each retained source record corresponds to exactly one array element, record order is preserved, and nested arrays remain nested. Confirm that any excluded empty lines were handled according to the stated policy and that no unresolved malformed record quietly disappeared from the report. Those checks produce a concrete outcome — either independently inspectable records with traceable errors, or one array document suited to the receiving interface. The JSON inspector on this site handles the middle case well: paste a single complete record and the tree shows its structure immediately, all parsed locally, so a suspect line from a log can be examined without importing the whole file.