
On this page
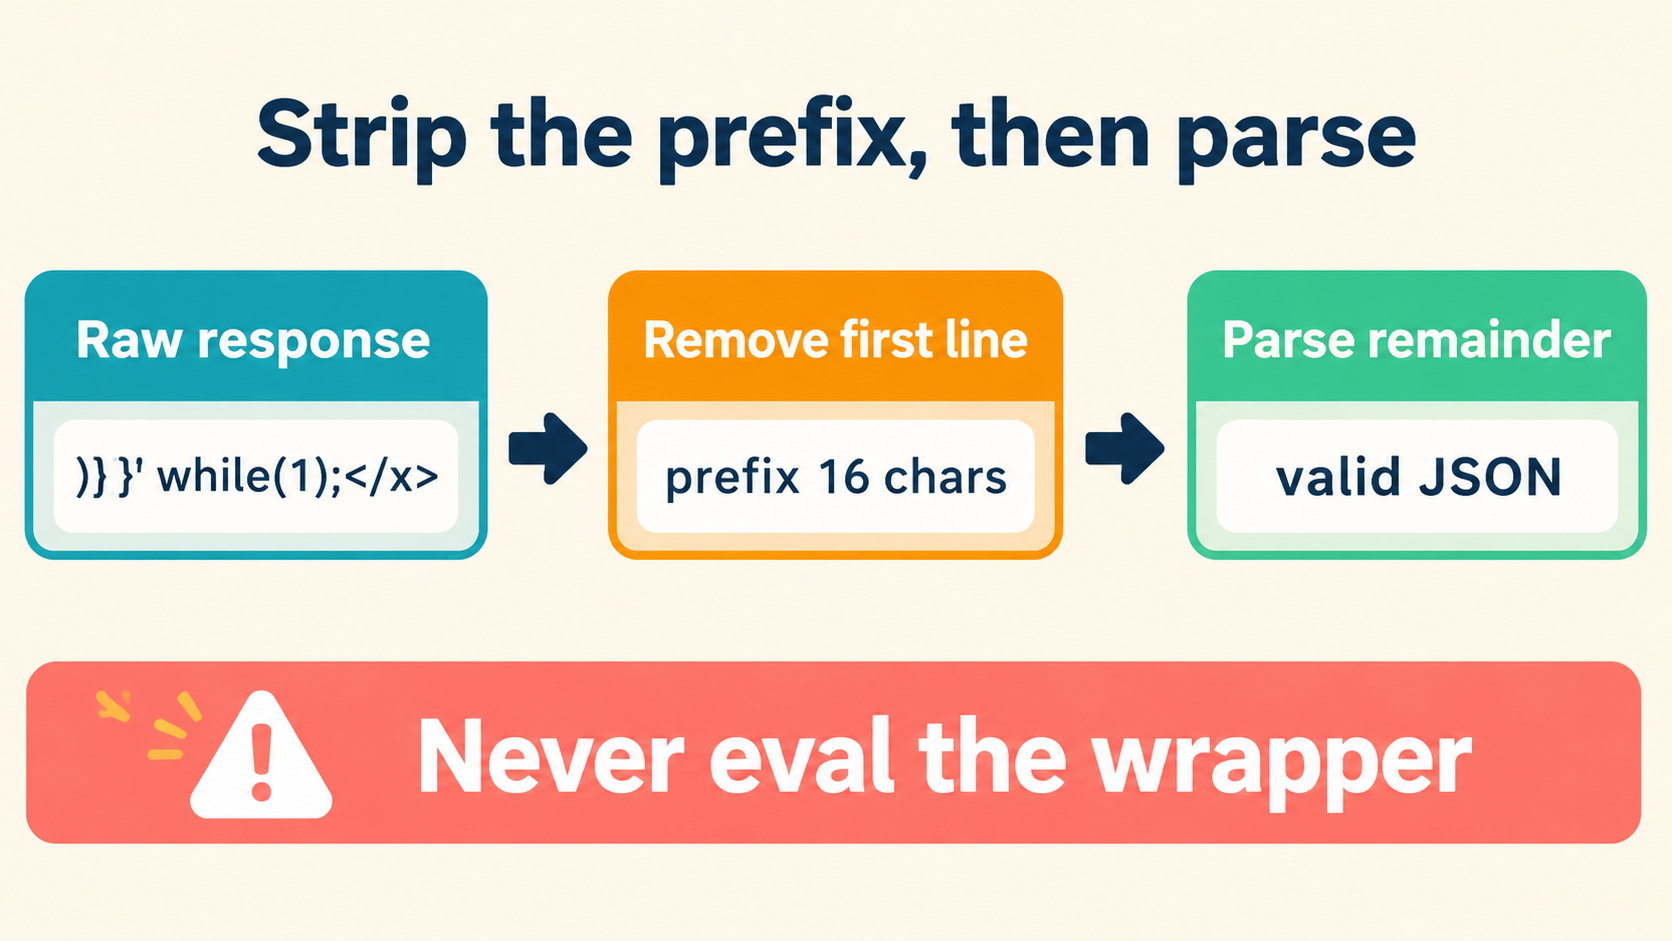
Recognize the Prefix Before Changing the Response
To inspect JSON behind a confirmed anti-XSSI prefix: preserve the original response, remove exactly that prefix from a working copy, then parse and format the remaining text. If the expected prefix does not match the beginning of the response, stop extraction and investigate the mismatch.
A valid JSON payload can sit behind leading text whose only job is to break naive script inclusion — that is the XSSI defense. Removing a confirmed prefix addresses that boundary; it does not repair errors inside the payload, and it does not establish how any parser handles every value.
For inspection, the essential distinction is between the endpoint’s intentional leading sequence and the JSON payload that follows it. Unfamiliar characters at the start of a response do not by themselves establish an anti-XSSI prefix. Confirm the sequence through the endpoint’s documentation or its maintainer, ask for the complete prefix including any separator or line break, and establish which responses use it. A sample helps you compare characters; appearance alone must not become the rule for deleting them.
- What exact sequence should appear at the beginning of this response?
- Does the documented sequence include a newline or other separator?
- Is that prefix expected for the particular response being inspected?
The complete response fails strict JSON parsing when a confirmed non-JSON prefix remains: the parser receives those leading characters as input, and a payload that looks valid farther down does not make them disappear. Keep that explanation separate from the diagnosis of an unfamiliar response — if the documented prefix is absent, you have an unexpected input to investigate, and deleting characters until parsing succeeds would bury that difference under a dependable-looking extraction rule.
Preserve the Original and Inspect the Response Body
Keep an unchanged copy of the response body before attempting extraction. Create a separate working copy, and record the prefix you intend to match — that gives you a stable reference for explaining what changed or investigating an error after removal. Four records, one per stage:
| Stage | What to retain | What it helps you check |
|---|---|---|
| Original response | The unchanged body text | What was received |
| Working copy | The text selected for extraction | Whether the prefix matches |
| Extracted JSON | The remainder after one removal | What the parser received |
| Formatted output | The parser’s rendered result | How the accepted data is presented |
When a viewer offers raw and formatted representations, compare them: does the raw view include the prefix, and does the formatted view explain any transformation? A convenient presentation should never become your only record of the input. If a viewer shows only a tree or formatted result, keep the original body separately — the rendered view alone cannot tell you which characters reached the parser or whether an earlier step changed them.
Preserving the stages also makes collaboration easier: another developer can compare the received response with the extracted text instead of reconstructing the transformation from a screenshot of formatted output.
Remove Exactly One Confirmed Leading Sequence
Make extraction narrow: compare the beginning of the working copy with the complete known prefix, then remove that sequence once — including any separator the endpoint documents as part of the prefix. Avoid adding cleanup steps merely because they make a particular sample pass. The sequence:
- Establish the exact, nonempty prefix expected for the response.
- Check whether the working copy starts with that entire sequence.
- If it does not match, report a prefix mismatch and keep the text unchanged.
- If it matches, take the remainder immediately after the prefix.
- Pass that remainder to the JSON parser.
Do not use global replacement — a leading-prefix operation must leave matching text elsewhere untouched, including text inside JSON strings. Do not search for the first opening brace or bracket either: that substitutes a guessed starting point for the endpoint’s documented boundary. Deleting the first line unconditionally is similarly unreliable; it assumes the prefix occupies exactly one line and the payload starts afterward, and neither assumption follows from unfamiliar leading text.
Avoid trimming or normalizing the working copy before matching unless the response contract explicitly calls for it — those operations change the input beyond the confirmed removal. If the prefix appears twice, remove only the single occurrence you were expecting and let the normal parsing step evaluate the rest:
// the entire extraction, kept honest:
function extract(body, prefix) {
  if (!body.startsWith(prefix)) {
    throw new Error('prefix mismatch — not removing anything');
  }
  return body.slice(prefix.length); // exactly one removal, position zero
}
// global replace, first-brace search, and unconditional line deletion
// all violate the contract above
Walk Through Input, Extraction and Formatted Output
This JavaScript example declares its own illustrative prefix, DEMO_PREFIX: — a demonstration fixture, not a documented prefix for any real endpoint. The colon belongs to the declared sequence, and the same sequence also appears inside a string value so you can verify it stays untouched:
const prefix = "DEMO_PREFIX:";
const original = prefix +
  '{"message":"DEMO_PREFIX: keep this text","count":2,"items":[true,null]}';

const workingCopy = original;

if (!workingCopy.startsWith(prefix)) {
  throw new Error("Expected prefix was not found at the start.");
}

const jsonText = workingCopy.slice(prefix.length);
const value = JSON.parse(jsonText);
const formatted = JSON.stringify(value, null, 2);
The preserved response is:
DEMO_PREFIX:{"message":"DEMO_PREFIX: keep this text","count":2,"items":[true,null]}
The extracted JSON is:
{"message":"DEMO_PREFIX: keep this text","count":2,"items":[true,null]}
The expected formatted output is:
{
  "message": "DEMO_PREFIX: keep this text",
  "count": 2,
  "items": [
    true,
    null
  ]
}
Prefix matching and removal happen explicitly, before JSON.parse receives the text. The response is parsed as data, never executed as code — that is the point of the defense being bypassed carefully rather than blindly. The string value retains DEMO_PREFIX: because extraction touches only the confirmed beginning of the response.
Two separate checks of the workflow are worth running: change the fixture’s leading sequence without changing prefix, and the explicit mismatch error should fire before parsing; keep the prefix but supply malformed payload text, and the failure should move to the parsing stage. Different stages failing differently is the proof the stages are actually separate.
// check 1 — mismatch fires early:
extract('OTHER:{"a":1}', 'DEMO_PREFIX:'); // Error: prefix mismatch
// check 2 — malformed payload reaches the parser:
JSON.parse(extract('DEMO_PREFIX:{"a":', 'DEMO_PREFIX:')); // SyntaxError
This example demonstrates manual extraction followed by parsing and formatting — not automatic prefix detection by an inspector. For a real response, replace the fixture values only after confirming the endpoint’s contract.
Investigate Errors That Remain After Extraction
First identify which stage failed. A prefix mismatch means the working copy did not begin with the sequence you expected. A parsing failure after a successful match means the extracted remainder was not accepted as JSON. Treating both as a generic “formatting error” makes the actual mismatch harder to locate.
For a prefix mismatch, compare the original beginning with the documented sequence — separators and line breaks included — and confirm you are inspecting the intended response. Do not proceed by trying progressively shorter prefixes until something parses; that search manufactures a rule you cannot defend.
For a parsing failure, inspect the extracted text beside the original. Check whether the body appears complete, whether unexpected text remains before or after the intended payload, and what the parser reports at the failure location. Compare the payload with the endpoint’s expected response. Avoid appending punctuation or deleting content merely to obtain formatted output — those are payload repairs, and they require a separate explanation:
// classify the failure before fixing anything:
try {
  const rest = extract(body, prefix);   // may throw: stage 1
  return JSON.parse(rest);              // may throw: stage 2
} catch (e) {
  // e.message names the stage — keep it, do not generalize it
}
Identify the Coordinate System Before Translating an Error
Record whether an error location refers to the extracted JSON, the working copy, or the preserved response. In the example, JSON.parse receives jsonText, so any location it reports must be interpreted against that input — not against the original response.
For absolute offsets using the same counting units and numbering convention, translating from extracted text to the original means adding the removed prefix’s length. Verify the conventions before doing the arithmetic; not every tool reports positions alike:
// offset translation, conventions verified:
const errAt = 12;                        // reported against jsonText
errAt + prefix.length;                   // 25 — position in the original
// if the prefix contained a line break, line/column translation
// needs the diagnostic's line numbering and line-ending treatment too
If the prefix contains line breaks, account for them when translating line and column locations: check the diagnostic’s line numbering, column counting, and treatment of line endings. Keep the reported location and its input stage alongside any translated location so another reader can reproduce the comparison.
Check Duplicate Keys and Number Preservation
Successful extraction establishes that the expected leading sequence was removed. Successful parsing establishes that the chosen parser accepted the remainder. Neither result documents how duplicate keys or numeric values are handled during inspection — those are separate policies, and they need separate verification before the formatted result is trusted:
| Concern | What to establish | What to compare |
|---|---|---|
| Repeated property names | Whether the tool rejects, reports, or resolves them, and how | Original occurrences against the rendered result |
| Large numeric values | Which values remain exact and how unsupported values are handled | Original numeric text against the output |
| Diagnostics | Whether warnings or errors accompany those cases | The diagnostic panel and formatted view together |
These are questions to verify, not promises about a particular implementation. Do not infer a duplicate-key policy from an ordinary object with unique names; formatting a small number successfully does not establish how the same pipeline handles a value beyond the safe-integer range.
// two probes the extraction fixture deliberately does not answer:
JSON.parse('{"a":1,"a":2}');           // which a survives? ask the tool's docs
JSON.parse('{"id":9007199254740993}'); // exact here — but check your formatter
The executable fixture deliberately uses unique property names and a small count; it demonstrates the extraction boundary without resolving parser-policy questions. Use representative cases from your actual requirements when checking documented behavior, and retain their original text for comparison. If the documentation does not answer a question, leave that behavior unresolved rather than describing the formatted result as fully preserving the input — a useful inspection report states what succeeded (prefix match, text reaching the parser, where inspection stopped) and keeps remaining uncertainty attached to the specific behavior that needs verification.
The discipline compresses cleanly: confirm the prefix, remove it once, parse what remains, and keep every stage’s record. The inspector on this site keeps its raw pane and parsed tree side by side — paste the fixture above, watch the extracted text parse, and confirm the in-string DEMO_PREFIX: survives untouched; the whole workflow runs locally, in one tab, with the original response never leaving your machine.